InferenceService · 무엇을
어떤 model을 어떤 resource·replica로 서비스할지 선언한다.
운영자가 주로 만들고 Git에서 version control할 객체다.
KServe는 모델을 계산하는 엔진이 아니라 모델 서버의 생명주기를 관리하는 Kubernetes control plane이다
CRDCustom Resource DefinitionInferenceService 같은 새 객체 종류를 추가하는 schema다.reconcile상태 맞추기InferenceServiceServingRuntimeLLMInferenceService
KServe가 request를 받아 직접 추론하지 않는다. controller는 운영 경로에 있고, 실제 request는 이미 만들어진 Service를 지나 vLLM·FastAPI 같은 model server로 간다. 그래서 controller가 잠시 재시작돼도 기존 Pod와 Service가 살아 있다면 serving data plane은 계속 동작할 수 있다.
InferenceService · 무엇을
어떤 model을 어떤 resource·replica로 서비스할지 선언한다.
운영자가 주로 만들고 Git에서 version control할 객체다.
ServingRuntime · 어떻게
model format을 실행할 image·command·port·protocol template다.
platform team이 검증해 여러 서비스가 재사용한다.
KServe controller · 계속 맞춘다
두 선언을 읽어 Deployment·Service·route를 만들고 상태를 관찰한다.
drift나 장애가 생기면 원하는 상태로 되돌린다.
한 문장으로는 InferenceService = model 배포 인스턴스, ServingRuntime = 검증된 실행 방법이다.
kind: InferenceServicemetadata: name: corp-chatspec: predictor: model: runtime: vllm-a100 storageUri: hf://org/model resources: limits: nvidia.com/gpu: "1" nodeSelector: accelerator.pool: a100-servingInferenceService를 etcd에 저장한다.vllm-a100의 image·command template에 model URI와 resource를 넣는다.InferenceService.status와 Ready condition을 갱신한다.spec을 바꾸면 이 흐름이 다시 돈다. Pod를 직접 고쳐도 controller의 원본은 InferenceService이므로 다음
reconcile에서 되돌아간다. 이것이 “선언형”의 실무적 의미다.
Standard mode는 일반 Kubernetes Deployment·Service를 사용한다. 상시 LLM은 model이 크고 cold start가 길며 stream이 오래 이어지므로 온프렘 환경에서는 가장 예측 가능한 출발점이다.
| 질문 | Standard InferenceService가 주는 답 |
|---|---|
| replica를 몇 개 유지할까 | Deployment replica·autoscaling policy |
| 죽은 model server는 누가 복구할까 | Kubernetes controller와 KServe 상태 관리 |
| endpoint를 어떻게 유지할까 | Service와 Gateway API·Ingress |
| image·model을 어떻게 바꿀까 | spec 변경과 rollout |
| 서로 다른 model runtime을 어떻게 표준화할까 | ServingRuntime catalog |
Knative mode는 CPU 예측 모델의 scale-to-zero처럼 명확한 이유가 있을 때 검토한다. GPU LLM에서 scale-to-zero는 수분짜리 model load를 첫 사용자 요청에 떠넘길 수 있다.
| runtime | 대상과 고정할 계약 |
|---|---|
vllm-spark | GB10 · ARM64 image·Spark driver/CUDA·한 node |
vllm-a100 | A100 full · x86_64 image·vLLM·GPU preset |
vllm-a100-mig | A100 MIG · model 크기·MIG resource·memory 여유 |
vllm-b300 | B300 · driver/CUDA·kernel·full-node 기준선 |
fastapi-cuda | custom model · port·readiness·SIGTERM·metric |
latest image나 범용 runtime 하나로 모든 GPU를 받지 않는다. runtime name이 architecture·가속기 계약을
드러내고, policy가 잘못된 image·nodeSelector·resource 조합을 거부해야 한다.
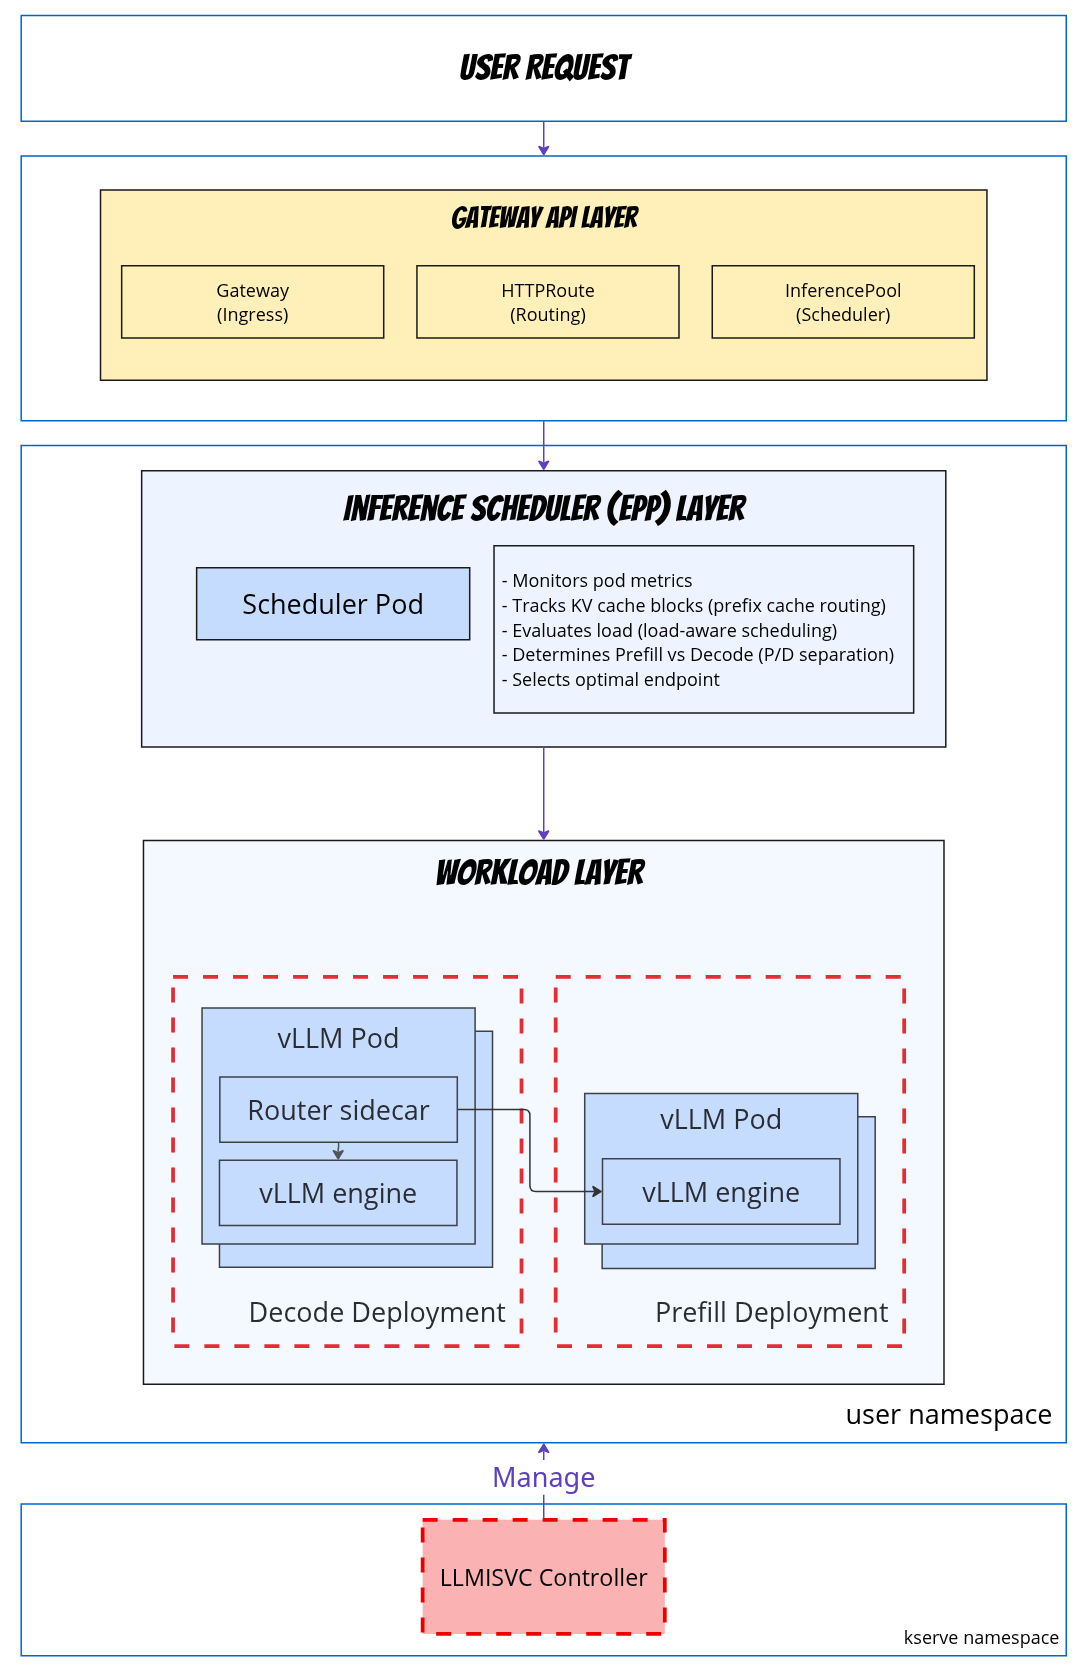
Standard path가 model Pod의 배포와 endpoint를 푼다면, LLMInferenceService는 큰 LLM을 여러 Pod와
지능형 router로 운영하는 topology를 푼다.
| 필요한 기능 | 추가되는 핵심 조각 |
|---|---|
| replica의 단순 round-robin보다 나은 routing | Gateway API Inference Extension의 InferencePool·EPP scheduler |
| 여러 node가 한 replica를 구성 | LeaderWorkerSet가 leader·worker를 한 단위로 관리 |
| 긴 prompt와 token 생성을 다른 pool로 분리 | prefill·decode workload와 그 사이의 KV 전달 |
| prefix cache·부하를 고려한 endpoint 선택 | scheduler plugin과 pod metric |
고급 경로에는 Gateway API CRD·Inference Extension·Gateway provider·LeaderWorkerSet 같은 의존성이 추가된다. 기능 이름이 매력적이라는 이유로 처음부터 설치하지 않는다. Standard에서 image·GPU·artifact· streaming을 먼저 합격시키고, 측정된 병목이 있을 때 이동한다.
InferenceService Ready condition → KServe controller event → Deployment desired / available → Pod event · readiness → model server log → GPU Operator와 node 상태상위 상태부터 내려가면 “KServe가 문제인지, 일반 Kubernetes 배치가 문제인지, model process가 문제인지, GPU 기반이 문제인지”를 빠르게 나눌 수 있다.
InferenceService·ServingRuntime·storage·cache 객체 지도.